JoVox: Joint Hierarchical Flow Matching for Lightweight Voxel Generation
arXiv preprint, 2026
Xiangjun Tang, Jianqi Chen, Peter Wonka
Abstract:
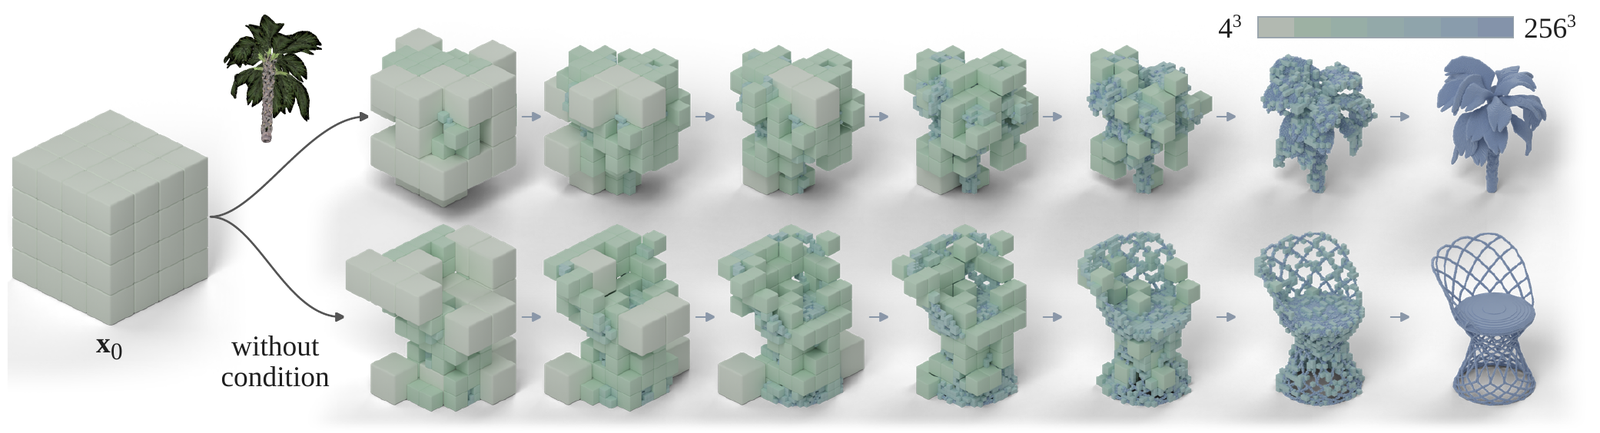
Generating high-fidelity voxels while keeping their lightweight nature remains an open problem in computer vision. Current generators are either high-fidelity but computationally heavy, or lightweight but of lower fidelity. Hierarchical methods keep the lightweight nature of voxels. However, their coarse levels, which decide where all finer cells can appear, are generated with the least information about the shape and are never revisited, so they are often plausible but wrong. Our key insight is to let finer cells take part in deciding coarse cells. To this end, we propose JoVox, a discrete flow matching framework that learns the joint distribution of all levels of the voxel hierarchy, instead of a separate distribution for each level, so that coarse cells can be predicted with finer cells already generated nearby. Within this framework, we further introduce a two-level prediction, which outputs the cells two levels finer at once instead of one level finer, halving the number of levels that the network processes and yielding voxels of higher fidelity. We also introduce an unmasking strategy that revisits early decisions once finer cells are generated and corrects inconsistencies in masked diffusion models. Our framework outperforms the baselines on both unconditional and image-conditioned voxel generation. Compared with the current state-of-the-art TRELLIS.2, we achieve $8\times$ higher training throughput, $1/15$ of the FLOPs in a forward pass, train on 4 vs. 32 GPUs, and obtain higher quality with an $11\%$ lower Chamfer distance.
bibtex:
@article{tang2026jovox,
  title={JoVox: Joint Hierarchical Flow Matching for Lightweight Voxel Generation},
  author={Tang, Xiangjun and Chen, Jianqi and Wonka, Peter},
  journal={arXiv preprint},
  year={2026}
}